Difference between revisions of "Loop"
m (→Feedback Loop - Scientific Discovery) |
|||
| (One intermediate revision by the same user not shown) | |||
| Line 308: | Line 308: | ||
[https://www.youtube.com/results?search_query=~Scientific+Discovery+loop+ai+machine+learning YouTube search...] | [https://www.youtube.com/results?search_query=~Scientific+Discovery+loop+ai+machine+learning YouTube search...] | ||
[https://www.google.com/search?q=~Scientific+Discovery+loop+ai+machine+learning ...Google search] | [https://www.google.com/search?q=~Scientific+Discovery+loop+ai+machine+learning ...Google search] | ||
| + | * [https://www.weforum.org/agenda/2020/11/scientific-discovery-must-be-redefined-quantum-and-ai-can-help/ Scientific discovery must be redefined. [[Quantum]] and AI can help | Dario Gil - World Economic Forum] | ||
| + | * [https://www.the-scientist.com/reading-frames/can-artificial-intelligence-make-scientific-discoveries--65790 Can Artificial Intelligence Make Scientific Discoveries? | Kartik Hosanagar - The Scientist] | ||
Discovery Loop is a newly formed startup backed by Google and led by former Google Chief Scientist Jeff Dean alongside a team of top AI researchers. The "loop" refers to the scientific method itself: proposing a hypothesis, running an experiment, and evaluating the results. By fully automating this process, the company aims to shift AI from a tool that answers questions into an active, autonomous researcher. | Discovery Loop is a newly formed startup backed by Google and led by former Google Chief Scientist Jeff Dean alongside a team of top AI researchers. The "loop" refers to the scientific method itself: proposing a hypothesis, running an experiment, and evaluating the results. By fully automating this process, the company aims to shift AI from a tool that answers questions into an active, autonomous researcher. | ||
| Line 315: | Line 317: | ||
* '''Self-Improving Systems:''' The company plans to act as its own first customer. They are starting by using these loops to optimize machine learning research itself. The AI will write code, test it, figure out what went wrong, and write better code. Once the system perfects its own underlying technology, it will expand to tackle global challenges like medicine and clean energy. | * '''Self-Improving Systems:''' The company plans to act as its own first customer. They are starting by using these loops to optimize machine learning research itself. The AI will write code, test it, figure out what went wrong, and write better code. Once the system perfects its own underlying technology, it will expand to tackle global challenges like medicine and clean energy. | ||
* '''The Team Building It:''' The founders include Jeff Dean and Sanjay Ghemawat, who co-designed the distributed computing backbone of Google, alongside Quoc Le and Oriol Vinyals, pioneers in deep learning and large-scale neural networks. | * '''The Team Building It:''' The founders include Jeff Dean and Sanjay Ghemawat, who co-designed the distributed computing backbone of Google, alongside Quoc Le and Oriol Vinyals, pioneers in deep learning and large-scale neural networks. | ||
| − | |||
| − | |||
| − | |||
| − | |||
<hr> | <hr> | ||
| Line 366: | Line 364: | ||
Some traders follow the trend, and some go against it. At I Know First we work on algorithmic strategies which are neither, we simply try an assess where the next opportunity is and provide stock market predictions. If this means to do what everyone else does, than why not. If it means going against when everyone else does, this is also fine. The tricky part is determining where this opportunities are, this article will discuss how to find opportunities in what can seem as total randomness. Markets are Complex, but not Unpredictable! There are two major misconceptions about the stock market. The first one is connected to the classical economic theory which claims markets to be efficient, and as such unpredictable. In this case trying to select one stock over another becomes useless, as no opportunity is ever better than the other. Both stocks are perfectly priced according to their opportunity and risk, with everyone having all information. However, the truth of the matter is that some people profit trading stocks while others lose – this by itself proves the market to be inefficient, and thus exploitable. While US markets are very efficient, and most information is available, not everyone interprets this information the same. [https://iknowfirst.com/stock-market-predictions-where-in-the-feedback-loop-is-your-portfolio Stock Market Predictions: Where In The Feedback Loop Is Your Portfolio? | I Know First] | Some traders follow the trend, and some go against it. At I Know First we work on algorithmic strategies which are neither, we simply try an assess where the next opportunity is and provide stock market predictions. If this means to do what everyone else does, than why not. If it means going against when everyone else does, this is also fine. The tricky part is determining where this opportunities are, this article will discuss how to find opportunities in what can seem as total randomness. Markets are Complex, but not Unpredictable! There are two major misconceptions about the stock market. The first one is connected to the classical economic theory which claims markets to be efficient, and as such unpredictable. In this case trying to select one stock over another becomes useless, as no opportunity is ever better than the other. Both stocks are perfectly priced according to their opportunity and risk, with everyone having all information. However, the truth of the matter is that some people profit trading stocks while others lose – this by itself proves the market to be inefficient, and thus exploitable. While US markets are very efficient, and most information is available, not everyone interprets this information the same. [https://iknowfirst.com/stock-market-predictions-where-in-the-feedback-loop-is-your-portfolio Stock Market Predictions: Where In The Feedback Loop Is Your Portfolio? | I Know First] | ||
| − | |||
| − | |||
{|<!-- T --> | {|<!-- T --> | ||
Latest revision as of 11:38, 17 September 2026
YouTube ... Quora ...Google search ...Google News ...Bing News
- Analytics ... Visualization ... Graphical Tools ... Diagrams & Business Analysis ... Requirements ... Loop ... Bayes ... Network Pattern
- Human-in-the-Loop (HITL) Learning
- Artificial Intelligence (AI) ... Machine Learning (ML) ... Deep Learning ... Neural Network ... Reinforcement ... Learning Techniques
- Perspective ... Context ... In-Context Learning (ICL) ... Transfer Learning ... Out-of-Distribution (OOD) Generalization
- Causation vs. Correlation ... Autocorrelation ...Convolution vs. Cross-Correlation (Autocorrelation)
- Embedding ... Fine-tuning ... RAG ... Clustering ... Recommendation ... Anomaly Detection ... Classification ... Dimensional Reduction. ...find outliers
- Algorithm Administration
- Policy ... Policy vs Plan ... Constitutional AI ... Trust Region Policy Optimization (TRPO) ... Policy Gradient (PG) ... Proximal Policy Optimization (PPO)
- Agents/Assistants ... Robotic Process Automation ... Personal Companions ... Productivity ... Email ... Negotiation ... LangChain
- Artificial Intelligence (AI) ... Generative AI ... Machine Learning (ML) ... Deep Learning ... Neural Network ... Reinforcement ... Learning Techniques
- Conversational AI ... ChatGPT | OpenAI ... Gemini | Google ... Claude | Anthropic ... Bing/Copilot | Microsoft ... Siri | Apple ... Meta ... Perplexity ... You ... phind ... Grok | xAI ... Groq ... Ernie | Baidu ... DeepSeek ... Alibaba
- Process Patterns, Loops and Emergence | Carlos E. Perez - Medium
- Autonomous Feedback Loops in LLM Agents | Research Team - Nature AI ... Advancements in self-correcting agentic architectures.
AI Loops and Agentic Workflows
When developers discuss "loops" in modern AI, they are referring to **Autonomous Agents** running in continuous feedback cycles rather than waiting for step-by-step human prompts.
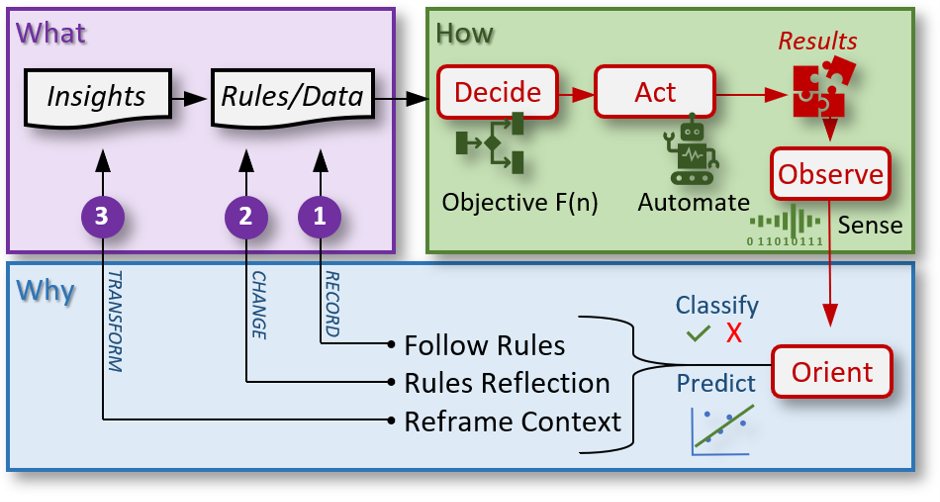
In traditional generative AI, the interaction is linear: you ask a question, the model generates an answer, and the process stops. In an agentic loop, the AI operates in a continuous cycle—often based on the OODA loop (Observe, Orient, Decide, Act) or similar cognitive architectures.
How an Agentic Loop Works
Instead of just answering a question, an Agent in a loop is given an overarching goal (e.g., "Research the top 5 competitors in this market and create a presentation"). The AI then enters a self-driven cycle:
- Observe / Perceive: The Agent looks at the current state of its environment. It might read a webpage, look at an error log, or take a screenshot of your desktop.
- Plan / Reason: The Agent breaks the main goal into smaller tasks and decides on the best next step. It might think, "I need to search Google for Competitor A."
- Act: The Agent uses an external tool. It might execute a Python script, click a button in a browser, or send an email.
- Reflect / Evaluate: This is the critical step that defines a loop. The Agent looks at the result of its action. If the web search failed or the code threw an error, the Agent catches the mistake, revises its plan, and loops back to step 1 to try a different approach.
<GenerateVideo uuid="VIDEO_OVERVIEW.1.1" source="offline"> </GenerateVideo>
Types of AI Loops
- Single-Agent Loops: Tools like Auto-GPT or OpenClaw use a single LLM to prompt itself repeatedly until a task is finished.
- Multi-Agent Loops: Frameworks like CrewAI or AutoGen set up multiple specialized Agents (e.g., a "Researcher" and a "Reviewer"). The Researcher finds information and loops it to the Reviewer. If the Reviewer spots an error, it loops the task back to the Researcher, creating a collaborative, self-correcting team.
- Human-in-the-Loop (HITL): The AI runs its cycle but pauses at critical moments to ask a human for approval before taking a major action, like sending a final email or spending money.
Observe–Orient–Decide–Act (OODA) Loop
YouTube search... ...Google search
The OODA loop is the cycle: Observe–Orient–Decide–Act ...emphasized that "the loop" is actually a set of interacting loops that are to be kept in continuous operation... developed by military strategist and United States Air Force Colonel John Boyd. Boyd applied the concept to the combat operations process, often at the operational level during military campaigns. It is now also often applied to understand commercial operations and learning processes. The approach explains how agility can overcome raw power in dealing with human opponents. It is especially applicable to cyber security and cyberwarfare. Wikipedia ... A Discourse On Winning and Losing | John R. Boyd - Air University Press
We’ve historically focused automation efforts on the “Act” portion but the real potential for new technologies is to address the prior 3 steps: Improving Observation: Improve the data itself with better sensing accuracy, timeliness, relevance, etc or improve our ability to use the data with higher throughput learning processes Improving Orientation: Improve the classification of the current state and the prediction of future states
Improving Decision: Improve the ability to choose between paths via better objective functions. How Artificial Intelligence is Closing the Loop with Better Predictions | Erik Trautman - HackerNoon]
|
|
Feedback Loop
YouTube search... ...Google search
- Gaming ... Game-Based Learning (GBL) ... Security ... Generative AI ... Games - Metaverse ... Quantum ... Game Theory ... Design
- Feedback | Wikipedia
- Closing the Loop: How Feedback Loops Help to Maintain Quality Long-Term AI Results | Natalie Fletcher - Clarifai
- So, What Actually Is a Feedback Loop? | Tina Nord - Ultimate Knowledge ...With feedback loops, a system is constantly in dialogue with itself.
- AI in the Feedback Loop: A Survey of Alternative Approaches | Karl-ErikÅrzén - ScienceDirect ...paper gives special attention to fuzzy control and expert control.
- Feedback Loops in Machine Learning | Ankur Goyal - Impair ...in spite of the immense benefits that Machine Learning offers, this technology has been very slow to take off, particularly in the enterprise world. At Impira, we believe a key reason for this is the lack of well-designed feedback loops that serve to continuously improve machine learning models.
- HP200A | Wikipedia ...oscillator to use a simple light bulb as the temperature-dependent resistor in its feedback network. Walt Disney bought eight HP200A for use in the production of Fantasia
- The Air Force Research Lab wants tools, techniques and innovative ideas for shortening the OODA Loop. | Aaron Boyd - Nextgov
any process where the outputs of a system are plugged back in and used as iterative inputs. Feedback loops exist just about everywhere. In nature, the evolutionary "arms race" between predators and prey is a classic example. In business, the practice of taking customer feedback (the output of a product or service) and using it to improve future processes is another commonly used feedback loop. Today, rapid advances in artificial intelligence (AI) and machine learning are helping businesses do more with data. These systems — and their ability to analyze an inhuman amount of data — allow businesses to adjust algorithms, workflows and processes on the fly. Get More Out Of Feedback Loops With AI | Arka Dhar - Forbes
|
|
Multi-Loop Learning
YouTube search... ...Google search
- How Artificial Intelligence Will Redefine Management | V. Kolbjørnsrud, R. Amico and R.J. Thomas
- Chris Argyris: theories of action, double-loop learning and organizational learning | Infed.org
- Donald Schon (Schön): learning, reflection and change | Infed.org
- Organisational learning: a critical review | Catherine L. Wang, Pervaiz K. Ahmed
- Single and double loop learning | Organizational Learning
- Double-loop learning | Wikipedia
- Re-Framing Perspectives | Patrick A. Trottier - The Institute Of Emergent Organizational Development and Emergent Change®
- Working visually: Record, Reflect, Reframe, Part 1 Part 2 | Kim S van den Berg
- Different Kinds of Learning (Loops of Learning) Adapted from “Field Guide to Consulting and Organizational Development”

|
|
|
|
|
|
Triple Golden OODA
YouTube search... ...Google search
- Context ... the next AI frontier
- Multi-Loop Learning
- Start With Why | Simon Sinek ...Wikipedia
- Observe–Orient–Decide–Act (OODA) Loop ...Wikipedia
- Perspective ... Context ... In-Context Learning (ICL) ... Transfer Learning ... Out-of-Distribution (OOD) Generalization
The Triple Golden OODA loop diagram depicts a hybrid of concepts from the Triple Loop concept inspired by Chris Argyris & Donald Schön's work on the Double Loop, Simon Sinek's Golden Circle in 'Start with Why', and Colonel John Boyd's Observe, Orient, Decide and Act (OODA) Loop from his ‘A Discourse On Winning and Losing'.
|
|
Feedback Loop - Peer Learning
YouTube search... ...Google search
- Education
- Decentralized: Federated & Distributed Learning
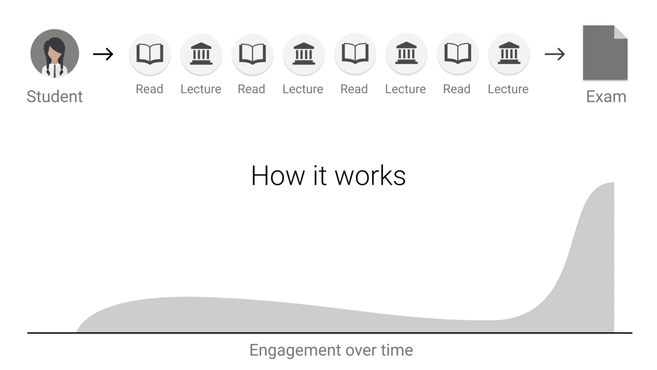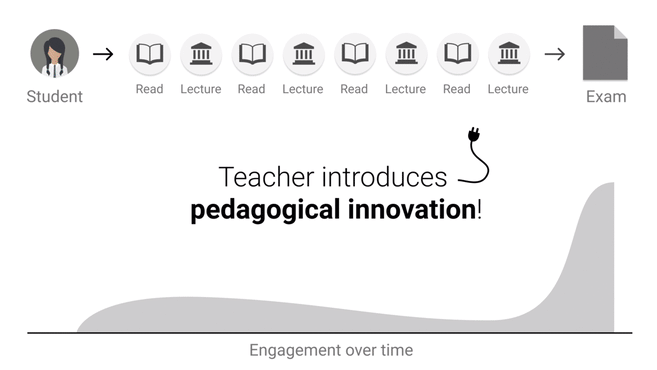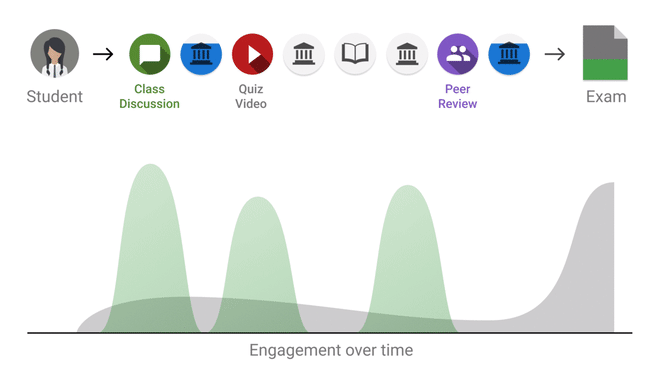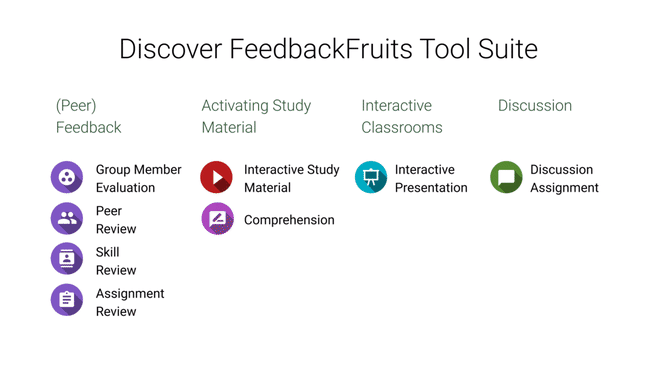
- FeedbackFruits
- The NIPS experiment | Eric Price - A blog on machine learning very broadly construed by Moritz Hardt
|
|
Feedback Loop - Creating Consciousness
YouTube search... ...Google search
- Life~Meaning ... Consciousness ... Creating Consciousness ... Quantum Biology ... Orch-OR ... TAME
- Three-Second Pause short story
- Life Sciences ... Evolutionary ... Bioinformatics ... Proteins ... Genome ... Genealogy ... Pharmaceuticals ... Chemistry
- You’re Living Inside a Prediction: Toward Predictive AI Consciousness
- Simulation ... Simulated Environment Learning ... World Models ... Minecraft: Voyager
- Artificial General Intelligence (AGI) to Singularity ... Curious Reasoning ... Emergence ... Moonshots ... Explainable AI ... Automated Learning
- Michio Kaku and the Mysteries of the Mind | Alyson Sheppard - Popular Mechanics ...The Future of the Mind: The Scientific Quest to Understand, Enhance, and Empower the Mind
- A Theory of Consciousness | Tyler Neylon - Medium
- Do Loops Explain Consciousness? | Martin Gardner - AMS.org ...Review of I Am a Strange Loop
- Strange Loop | Wikipedia ...The "strangeness" of a strange loop comes from our way of perception
- Godel, Escher, Bach: an Eternal Golden Braid | Douglas R. Hofstadter
|
|
|
|
Feedback Loop - Scientific Discovery
YouTube search... ...Google search
- Scientific discovery must be redefined. Quantum and AI can help | Dario Gil - World Economic Forum
- Can Artificial Intelligence Make Scientific Discoveries? | Kartik Hosanagar - The Scientist
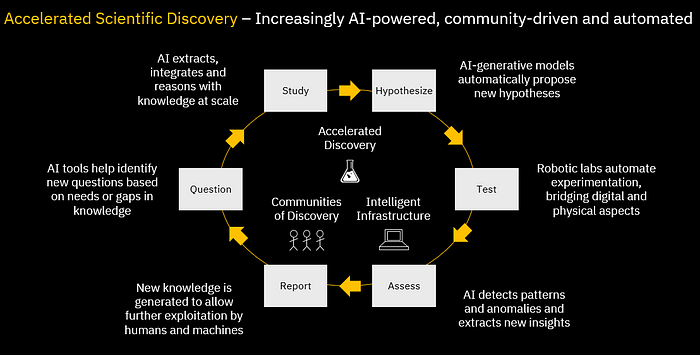
Discovery Loop is a newly formed startup backed by Google and led by former Google Chief Scientist Jeff Dean alongside a team of top AI researchers. The "loop" refers to the scientific method itself: proposing a hypothesis, running an experiment, and evaluating the results. By fully automating this process, the company aims to shift AI from a tool that answers questions into an active, autonomous researcher.
- Automating the Scientific Method: Traditionally, human teams test ideas sequentially. Discovery Loop is building systems that let AI handle the entire propose-run-evaluate cycle. Think of it like a self-driving car, but for scientific research. Instead of a scientist manually steering the experiment, the AI navigates the data, adjusts its route based on roadblocks, and drives toward a solution.
- Extreme Parallelism: Because the loop is automated, the system can run thousands of experiments simultaneously. If finding a new battery material is like searching a massive maze, human researchers walk down one path at a time. An automated loop drops thousands of explorers into the maze at once, drastically shrinking the time it takes to find the exit.
- Self-Improving Systems: The company plans to act as its own first customer. They are starting by using these loops to optimize machine learning research itself. The AI will write code, test it, figure out what went wrong, and write better code. Once the system perfects its own underlying technology, it will expand to tackle global challenges like medicine and clean energy.
- The Team Building It: The founders include Jeff Dean and Sanjay Ghemawat, who co-designed the distributed computing backbone of Google, alongside Quoc Le and Oriol Vinyals, pioneers in deep learning and large-scale neural networks.
The paradigm shift will be from AI used for analysing the data which has already been obtained, to AI deciding what to measure next. Why Artificial Intelligence Will Enable New Scientific Discoveries - Andrew Briggs - Graphcore
[Quantum Computing and AI to Enable Our Sustainable Future | Katia Moskvitch - ]IBM

|
|
Feedback Loop - Stock Market Predictions
YouTube search... ...Google search
Why you can beat the market, even when it does not seem so. The importance of loops, patterns, and predictable events. Random events are don’t measure risks, and should not affect your decision making. Some traders follow the trend, and some go against it. At I Know First we work on algorithmic strategies which are neither, we simply try an assess where the next opportunity is and provide stock market predictions. If this means to do what everyone else does, than why not. If it means going against when everyone else does, this is also fine. The tricky part is determining where this opportunities are, this article will discuss how to find opportunities in what can seem as total randomness. Markets are Complex, but not Unpredictable! There are two major misconceptions about the stock market. The first one is connected to the classical economic theory which claims markets to be efficient, and as such unpredictable. In this case trying to select one stock over another becomes useless, as no opportunity is ever better than the other. Both stocks are perfectly priced according to their opportunity and risk, with everyone having all information. However, the truth of the matter is that some people profit trading stocks while others lose – this by itself proves the market to be inefficient, and thus exploitable. While US markets are very efficient, and most information is available, not everyone interprets this information the same. Stock Market Predictions: Where In The Feedback Loop Is Your Portfolio? | I Know First
|
Feedback Loop - The AI Economist
YouTube search... ...Google search
Optimal Tax Design as Learned Reward Design Using Reinforcement Learning. Reinforcement learning is a powerful framework in which Agents learn from experience collected through trial-and-error. We use model-free RL, in which Agents do not use any prior world knowledge or modeling assumptions. Another benefit of RL is that Agents can optimize for any objective. In our setting, this means that a tax policy can be learned that optimizes any social objective, and without knowledge of workers’ utility functions or skills. The AI Economist: Improving Equality and Productivity with AI-Driven Tax Policies | S. Zheng, A. Trott, S. Srinivasa, N. Naik, M. Gruesbeck, D. Parkes, and R. Socher - Einstein.ai]

|
Feedback Loop - Synthetic
YouTube search... ...Google search
|
Feedback Loop - Allostasis & Homeostasis
- Life~Meaning ... Consciousness ... Creating Consciousness ... Quantum Biology ... Orch-OR ... TAME
- Adrenal Health, Stress Adaptation & Homeostasis |YourHormonesInc - YouTube video
- Allostasis | Wikipedia
- Homeostasis | Wikipedia
- Allostasis the process of maintaining stability by changing the body’s operating settings in response to context and predicted demand—your brain and body anticipate needs (stress, exercise, threat, illness, time of day) and adjust hormones, autonomic output, and immune activity to match the situation.
Before a speech: your heart rate rises, cortisol may increase, and blood pressure shifts before you start talking → Allostasis
- Homeostasis is the state of steady internal, physical, and chemical conditions maintained by living systems. This is the condition of optimal functioning for the organism and includes many variables, such as body temperature and fluid balance, being kept within certain pre-set limits (homeostatic range). Homeostasis operates primarily through negative feedback loops. When a variable changes, the body triggers a response to reverse that change to maintain equilibrium.
After the speech ends: those values return toward baseline through feedback corrections → Homeostasis
Allostasis as the strategy (adapt to demand) and Homeostasis as the fine-tuning mechanics (keep variables in safe ranges).
How they’re different
- Goal
- Homeostasis: keep a variable near a set range.
- Allostasis: keep the organism functioning well by adapting the set range and related systems to the moment.
- Timing
- Homeostasis: mostly reactive (corrects after deviation).
- Allostasis: often predictive/anticipatory (adjusts before or during expected demand).
- Control style
- Homeostasis: local “thermostat” loops (negative feedback).
- Allostasis: coordinated, whole-system regulation (brain-driven orchestration across multiple systems).
- Cost concept
- Homeostasis: not usually framed as “costly” unless failing.
- Allostasis: emphasizes wear-and-tear from chronic activation—allostatic load.
Homeostatic Control System A homeostatic control system consists of three functional components:
- Receptor (Sensor): Detects a change in the environment (stimulus).
- Control Center: Processes the information and signals the effector (e.g., the brain).
- Effector: Carries out the necessary adjustment to restore balance.
The term was coined by physiologist Walter Bradford Cannon in 1926. It is derived from the Greek words:
- hómoios (Template:Lang), meaning "similar"
- stásis (Template:Lang), meaning "standing still"
Homeostasis & Allostasis: An Evolutionary Perspective With Consciousness
Life survives by keeping its internal conditions in a workable range. Early life mostly did this with Homeostasis (reactive feedback). As nervous systems evolved, organisms gained Allostasis (predictive, context-sensitive regulation). What we call conscious experience may be one of the tools that helps organisms coordinate allostatic control across the whole body—especially when tradeoffs, uncertainty, or social complexity are involved.
Homeostasis came first: the ancient “stay alive” machinery Homeostasis is evolution’s baseline: keep core variables (ions, pH, temperature, glucose, oxygen, hydration) within survivable bounds.
- Single cells: membrane pumps, ion channels, osmotic regulation, energy balance (ATP) — fast local loops.
- Multicellular life: internal transport (circulation), compartment control, hormonal signaling — keeping the “internal ocean” stable enough for specialized tissues.
Key evolutionary point: Homeostasis works best when the environment is fairly predictable and when local feedback loops can correct deviations quickly.
Allostasis emerged with nervous systems: “stability through change” Allostasis is what you get when an organism can anticipate, learn, and coordinate multiple systems at once.
- Prediction: adjust physiology before demand hits (fight/flight, exercise, cold exposure, feeding).
- Coordination: align heart, lungs, immune tone, attention, and behavior toward the same goal.
- Tradeoffs: choose a “good enough” body state for the situation (e.g., temporarily raise blood pressure to escape, even if it’s not ideal long-term).
Key evolutionary point: Allostasis becomes valuable when:
- the environment is variable,
- the organism is mobile,
- the organism must make fast choices under uncertainty.
- and playing dead
Where consciousness fits: interoception + choice under uncertainty A useful way to connect consciousness to regulation is interoception — sensing internal body states (heartbeat, breathing, gut signals, temperature, inflammation, hormonal state).
- Much interoceptive control is unconscious (reflex loops in the brainstem/hypothalamus).
- Some interoceptive information becomes conscious feelings (hunger, thirst, nausea, calm, anxiety, “wired/tired,” pain).
One evolutionary hypothesis: consciousness helps Allostasis when the organism needs flexible control across time:
- planning (“If I keep running, will I overheat?”)
- learning (“That food made me sick—avoid it.”)
- social prediction (“If I challenge him, what happens next?”)
- conflict resolution (“I’m scared, but I still need to do this.”)
A layered control stack: from reflex → feeling → deliberation You can think of regulation as a stack of increasingly “expensive” control systems:
- Layer A
- Local Homeostasis (fast, automatic)
- Cells and organs self-regulate (ion balance, local blood flow, basic reflexes).
- Layer B
- Body-wide Allostasis (coordinated, mostly automatic)
- Brainstem + hypothalamus + autonomic and endocrine systems shift setpoints based on context (stress response, circadian rhythm, fever response).
- Layer C
- Conscious control (slow, flexible, meaning-driven)
- Cortex can simulate futures, apply goals/values, and reshape behavior to prevent future instability (choose shelter, negotiate, delay gratification, seek help).
Why it matters: consciousness is not required for most homeostatic corrections—but it may be crucial for complex allostatic problems where the “right” action depends on goals, predictions, and social context.
Emotions as “Allostatic programs” From this lens, emotions aren’t random “extras.” They can be seen as packaged action-and-body-state programs:
- Fear biases attention + raises arousal to escape threats.
- Anger mobilizes energy for confrontation and boundary enforcement.
- Sadness can promote withdrawal/conservation and social support seeking.
- Joy/interest can promote exploration and learning when safe.
These states are Allostatic because they change physiology and behavior together to manage risk and opportunity.
When the system misfires: Allostatic load Allostasis is powerful, but it has a cost when it’s chronically engaged:
- persistent stress physiology
- disrupted sleep/circadian rhythms
- metabolic strain
- inflammatory changes
Allostatic load is the “wear-and-tear” that shows up when the body keeps paying short-term survival costs without recovery—often a mismatch between ancient regulatory systems and modern persistent stressors.
Takeaway
- Homeostasis is the ancient reactive core: correct deviations to protect life.
- Allostasis is the evolved upgrade: predict, coordinate, and adapt setpoints to meet situations.
- Consciousness may be one of evolution’s tools for higher-level Allostatic control—helping an organism integrate internal signals with goals, learning, and social reality when simple reflexes aren’t enough.
Examples
| Process | Scenario | Homeostatic Response |
|---|---|---|
| Thermoregulation | Hyperthermia (Too hot) | Sweating (evaporative cooling) and vasodilation (widening of blood vessels to release heat). |
| Hypothermia (Too cold) | Shivering (muscle heat generation) and vasoconstriction (narrowing of blood vessels to conserve heat). | |
| Glucoregulation | Hyperglycemia (High blood sugar) | The pancreas releases insulin, causing cells to absorb glucose. |
| Hypoglycemia (Low blood sugar) | The pancreas releases glucagon, causing the liver to release stored glucose. | |
| Osmoregulation | Dehydration | The kidneys concentrate urine to conserve water; the hypothalamus stimulates thirst. |
Vagus Nerve
Vagus nerve acts like a two-way control cable between your organs and your brainstem—constantly measuring internal conditions and then nudging things back toward “normal.” Most vagus fibers are sensory (afferent)—they carry status updates from your organs up to the brain (often cited around ~80% afferent). Those signals primarily land in the nucleus tractus solitarius (NTS) in the medulla, a major “autonomic dashboard” that integrates input from the cardiovascular, respiratory, and digestive systems. Then the brain sends motor (efferent) vagal output back down (via nuclei like the nucleus ambiguus and dorsal motor nucleus) to adjust organs—usually in a calming, “rest-and-digest” direction.
Organ state changes → vagal sensory input → NTS integrates → vagal output → organ function shifts → state normalizes
- Blood pressure & heart-rate control (baroreflex) - Sensors in major arteries detect stretch/pressure and signal the brainstem; the NTS then helps drive vagal output that slows the heart when pressure is high (and relaxes vagal braking when pressure is low).
- Breathing–heart coordination (respiratory sinus arrhythmia) - Your heart rate naturally speeds a bit on inhale and slows on exhale; that rhythm reflects tight coupling between respiration networks and cardiac vagal control pathways.
- Gut “status,” satiety, and digestion (vagovagal reflexes) - Vagal sensory neurons detect things like stomach stretch and digestive signals and report to the brainstem; vagal output helps tune motility and secretion.
- The “inflammatory reflex” (immune homeostasis) - There’s evidence for a vagus-linked reflex where vagal signaling can dampen excessive cytokine release (often described as the cholinergic anti-inflammatory pathway), involving acetylcholine signaling and α7 nicotinic receptors on immune cells in experimental models
AlphaFold 2
DeepMind AlphaFold can help researchers understand receptors/ion channels/drug targets that sit upstream of autonomic signaling. (think adrenergic + muscarinic GPCRs, serotonin receptors, nicotinic receptors, cardiac ion channels like hERG/Kv11.1, etc.).
- 3D structure when no experimental model exists: DeepMind AlphaFold can generate a workable 3D fold for hard targets (especially membrane proteins), giving researchers a structural starting point for autonomic-relevant receptors and channels.
- Druggable pocket mapping: With a predicted structure, researchers can identify and compare likely orthosteric/allosteric pockets and map known functional residues to guide selectivity and SAR hypotheses.
- Signaling-complex hypotheses: DeepMind AlphaFold (including multimer approaches) can model receptor–transducer interfaces (e.g., GPCR–G protein) to propose coupling-selectivity determinants and testable interaction residues.
- Complexes with ligands/ions (AlphaFold 3): DeepMind AlphaFold 3 can propose bound geometries for proteins with small molecules, ions, and modified residues, helping frame how upstream autonomic targets may engage drugs or cofactors.
- Channel gating and state-dependent binding: Structural models can suggest pore architecture and gating features that help explain why some drugs bind preferentially to specific channel states relevant to excitability control.
- Variant-to-mechanism interpretation: By placing mutations on a structure, researchers can hypothesize whether variants affect folding/trafficking, ligand binding, gating, or signaling interfaces and then design focused validation assays.
- Faster experimental design and interpretation: DeepMind AlphaFold models help pick construct boundaries and stabilizing changes and can speed cryo-EM/mutagenesis planning by providing a structural scaffold for iterative testing.
Active Inference Loop
YouTube search... ...Google search
Active inference is a framework that treats intelligent systems like scientists instead of passive pattern-matching engines. Most modern machine learning models operate as giant autocomplete algorithms. They compress massive datasets to guess outputs, but if a scene deviates from their training data, they don't adjust well. Their confidence stays high even when their performance drops. Active inference takes a different approach. It unifies perception, learning, and action into a single continuous loop. Instead of just reacting to the world, an Agent anticipates what will happen next and actively updates its internal model when reality doesn't match its predictions.
This framework gives an Agent an explicit generative model that interacts with the outside world through a sensory and action boundary known as a Markov blanket. The Free Energy Principle and its role in Active Inference represent a shift in how we understand intelligence, moving from a system that passively reacts to stimuli to one that actively anticipates and structures reality.
The Free Energy Principle At its core, the free energy principle suggests that intelligent systems, whether biological or artificial, behave as if they are constantly trying to minimize Variational Free Energy.
- What it measures: It acts as a score of the mismatch between the system's internal model of the world and its actual sensory observations, while also penalizing overly complex internal models.
- The Goal: By minimizing this "surprise," the system maintains stability and keeps itself in a predictable, safe state. If a system is constantly shocked by its environment, it signifies that it lacks understanding or control over its circumstances.
Active Inference Framework Active inference extends this by unifying perception, learning, and action into a single loop. It uses the free energy principle to guide how an Agents interacts with the world:
- Perception as Inference: Instead of recording the world passively, the brain (or AI Agent) maintains hypotheses about "hidden causes" it cannot directly see. It constantly updates these beliefs based on sensory evidence.
- Action as Sampling: An Agent doesn't just infer the world; it actively chooses actions that help it "sample" the world to resolve uncertainty. For example, if you are unsure about an object, you might change your perspective to get a better view rather than just relying on the initial, noisy signal.
- Solving the Exploration-Exploitation Dilemma: Unlike traditional AI that relies on hand-designed reward signals, Active Inference replaces this with the minimization of expected free energy. This naturally drives an Agent to explore the environment to gain information (reduce uncertainty) while also exploiting what it knows to achieve preferred outcomes.
Essentially, intelligence is reframed as self-evidencing. It is a continuous process of acting to confirm and refine one's understanding of the world while avoiding states that would overwhelm the system with unpredictability. Ultimately, integrating these structured mechanics with large language models offers a practical path toward efficient, explainable AI that explicitly understands the limits of its own knowledge.
|
Markov Blanket
YouTube search... ...Google search
To understand how an AI Agent or a biological organism interacts with the world, you have to define where the system ends and the environment begins. This boundary is called a Markov blanket. It is a mathematical concept that acts as a statistical shield. It separates the internal states of a system from the external states of the universe.
Because of this boundary, the internal workings of a system are conditionally independent of the outside world. Everything the system needs to know about the environment is contained entirely within the blanket itself. The Markov blanket consists of two crucial parts:
- Sensory states: These take in information from the outside world but are not influenced by the system's internal states.
- Active states: These push influence out into the world but are not directly altered by external forces.
By maintaining this boundary, an intelligent system can sample the world through its sensors and act upon it, all while keeping its internal model intact. You never access reality directly. Instead, you constantly update your beliefs based on the signals crossing your Markov blanket. This concept forms the foundation of how systems self-organize, survive, and make sense of their surroundings without simply dissolving into chaos.
|
|
Recursion
YouTube search... ...Google search
|
